Inkling 2 Mini leads open models under 100 billion parameters on agentic coding benchmarks, ships under the Apache 2.0 license, and runs on a Mac with 32 GB of memory.
- Thinking Machines has released Inkling 2 Mini, an open model that runs 12 of its 24 layers three times for each token
- 26.4 billion parameters, 5.4 billion active per token, handles both text and images, 1 million token context window
- Leads open models under 100 billion parameters in agentic coding: 48.2% on DeepSWE v1.1, 46.5% on Vals Index v2.2
- Runs locally on a Mac with 32 GB of memory or more, or on an NVIDIA DGX Spark, with downloads on Hugging Face
Table of Contents
How a looped transformer works
Thinking Machines has released Inkling 2 Mini, a looped transformer: some of its layers are run repeatedly for every token. In Inkling 2 Mini, 12 of the 24 layers are run three times in a row. According to the company, this gives the model extra internal reasoning time without writing any additional words out loud, so it reaches the right answer with fewer tokens.
On specs, this is an open mixture-of-experts (MoE) model with 26.4 billion parameters, of which the company says only 5.4 billion are active per token because of the layer-looping approach. The model handles both text and images and has a 1 million token context window. It is released under the Apache 2.0 license, so users can download it and use it fairly freely.
Benchmark results
In agentic coding, Inkling 2 Mini ranks first among open models under 100 billion parameters, scoring 48.2% on DeepSWE v1.1 and 46.5% on Vals Index v2.2. What stands out is that the result comes from a model well short of the 100 billion mark, with only 26.4 billion parameters in total.
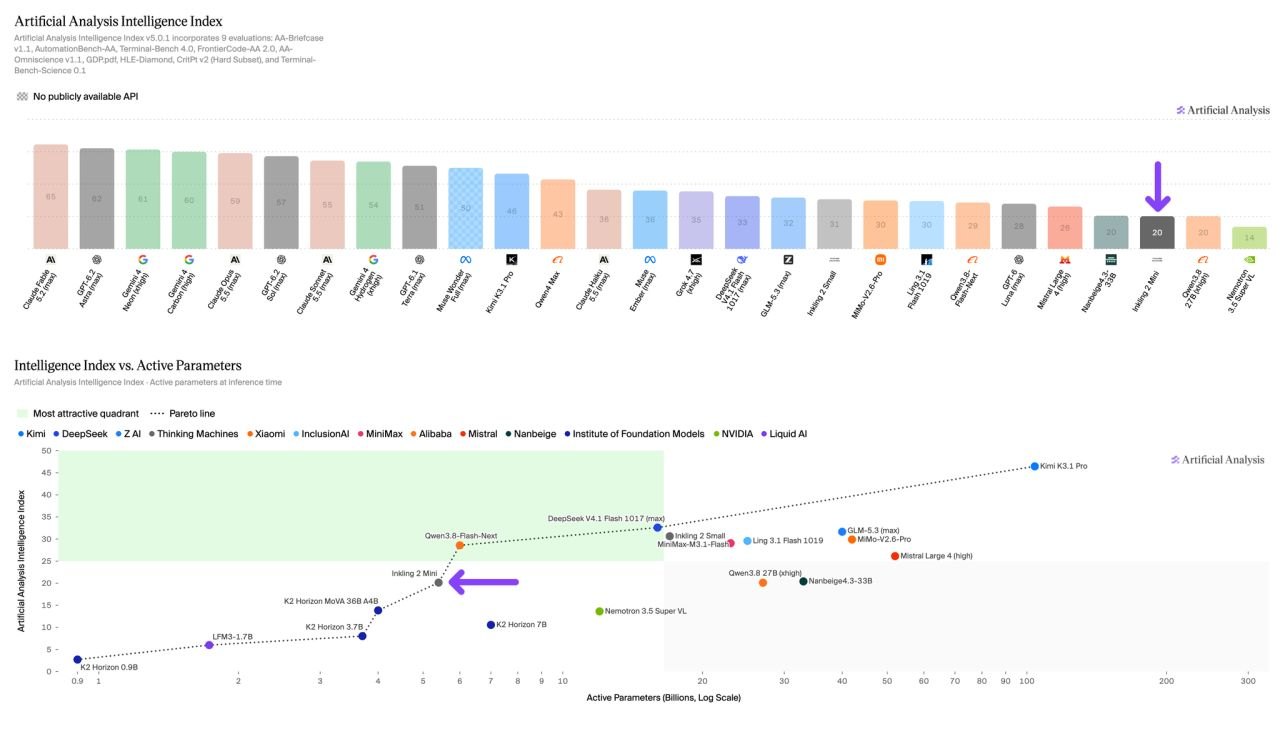
On the Artificial Analysis Intelligence Index, Inkling 2 Mini scores 20, on par with Qwen3.8 27B, but at roughly one-sixth of the cost and four times the speed. The figures suggest that repeating a portion of the layers may be a way to gain quality without inflating the parameter count.
Running it locally and downloading it
For local use, Inkling 2 Mini runs on Macs with 32 GB of memory or more, as well as on the NVIDIA DGX Spark. You can download the weights from Hugging Face, along with a research version that lets you change the number of loop iterations. Anyone who just wants to see what the model can do can try the version available in the Tinker Playground.
Migovi sees the value of Inkling 2 Mini more in its direction than in its numbers. Looping half of the layers so the model thinks longer and lands on an answer with fewer tokens is a way to improve quality without paying for it with a bulky model. That said, the leading scores were only just published, and more people need to test it on real-world work before any conclusion can be drawn. For users in Vietnam, an Apache 2.0 open model that runs on a 32 GB Mac is worth trying for anyone who wants a coding assistant running right on their own machine. If your machine has less memory, it is better to wait for the company or the community to state the minimum requirements clearly before downloading.
Source: The Decoder (AI)
Reviewed by: Hero Association